· 23 min read
Understanding The Intuitive Idea of Attention
Table of Contents
- The Information Bottleneck in Vanilla Seq2Seq
- The Intuitive Idea of Attention
- Mathematical Formulation of Attention
- Deep Dive: Step-by-Step Mathematical Derivations
- Detailed Example: Bengali→English Translation
- Bahdanau vs. Luong Attention: Architectural Deep Dive
- Mathematical Properties and Theoretical Analysis
- Information-Theoretic Perspective
- Gradient Flow and Training Dynamics
- Real-World Applications
- Quick Revision Summary
- References
The Information Bottleneck in Vanilla Seq2Seq
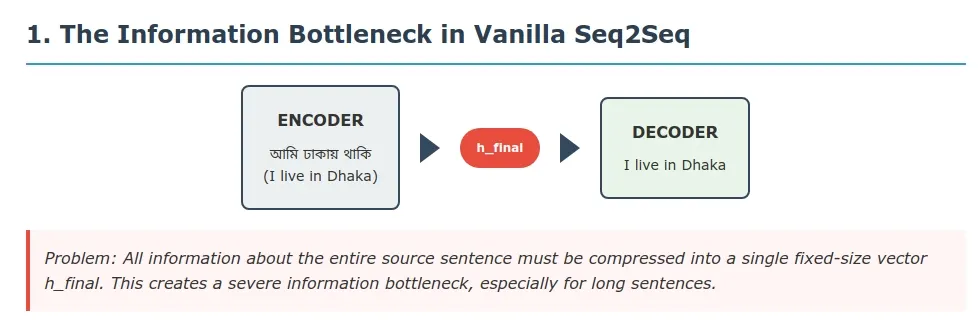
In a basic encoder–decoder (seq2seq) model, the encoder compresses an entire input sequence into a single fixed-size vector (often the last hidden state ). The decoder then generates all outputs from this one vector. Formally:
Encoder: . Decoder: .
This creates a severe information bottleneck. All information about a sentence of length must be squashed into one vector. As Bahdanau et al. explain, a fixed-length context tends to forget early words and degrades for long sentences. In practice, translation accuracy drops sharply as sentence length grows. Moreover, the decoder sees a static context: it uses the same to predict every output word. Intuitively, this is like trying to translate by looking at a blurry snapshot of the entire source sentence – you cannot dynamically focus on particular words. Attention mechanisms were introduced precisely to break this bottleneck, as described next.
The Intuitive Idea of Attention
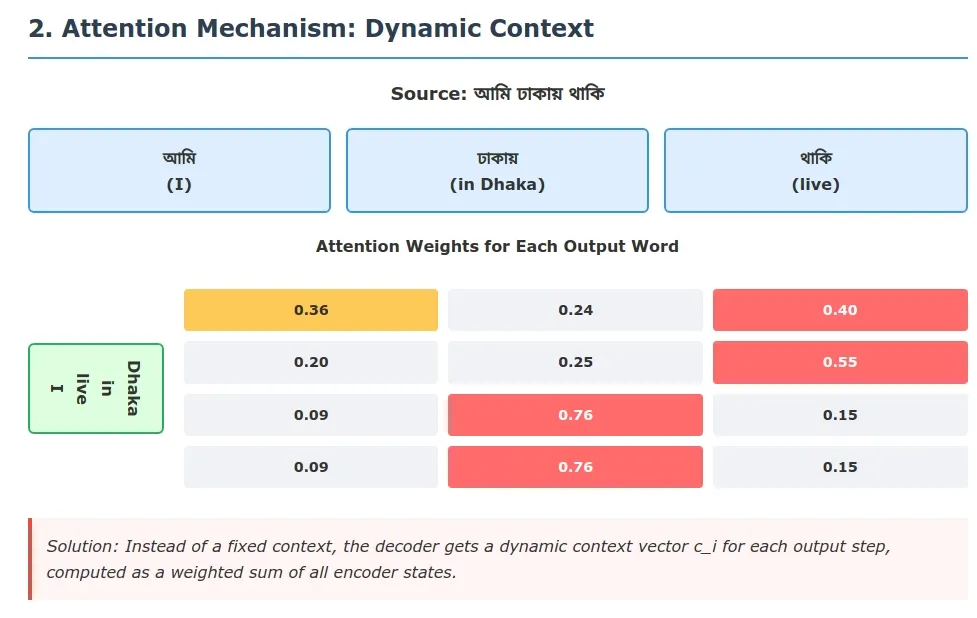
Instead of a fixed summary, attention lets the model focus on different parts of the input when generating each output. In human terms, when translating we often concentrate on one phrase at a time. For example, translating “আমি বাংলাদেশে বাস করি” → “I live in Bangladesh”: a human translator might first focus on “আমি” and say “I”, then focus on “বাস করি” to say “live”, and finally on “বাংলাদেশে” for “in Bangladesh”.
Attention is like a movable spotlight over the input sequence: for each output position , the model assigns a weight (the “brightness” on word ) and draws a context vector as a weighted summary of the input. As Xu et al. demonstrate in image captioning, an attention-based model can automatically “fix its gaze” on salient objects (here, words or image regions) when generating each word. Concretely, the attention weights form a probability distribution over source positions (summing to 1), so the decoder can softly attend to the most relevant words. This “soft alignment” is learned end-to-end.
Mathematical Formulation of Attention
Attention introduces a few new quantities alongside the usual seq2seq variables. Suppose the encoder produces hidden states
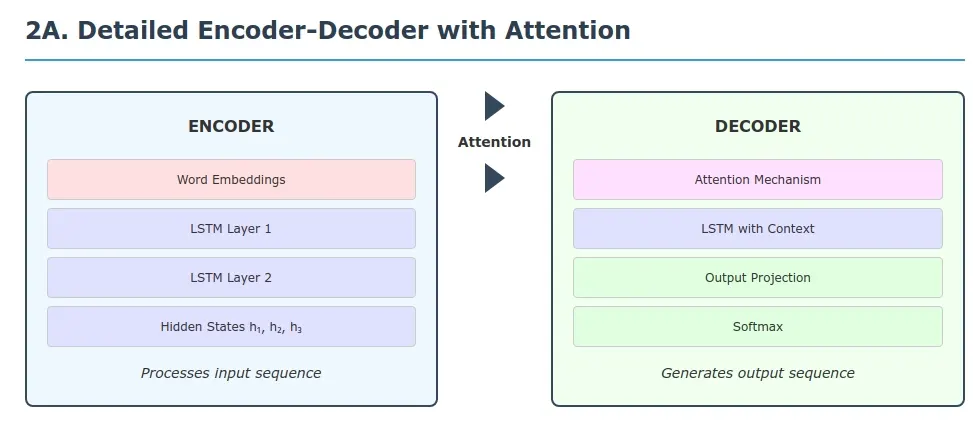
for each of the input tokens. The decoder has hidden states
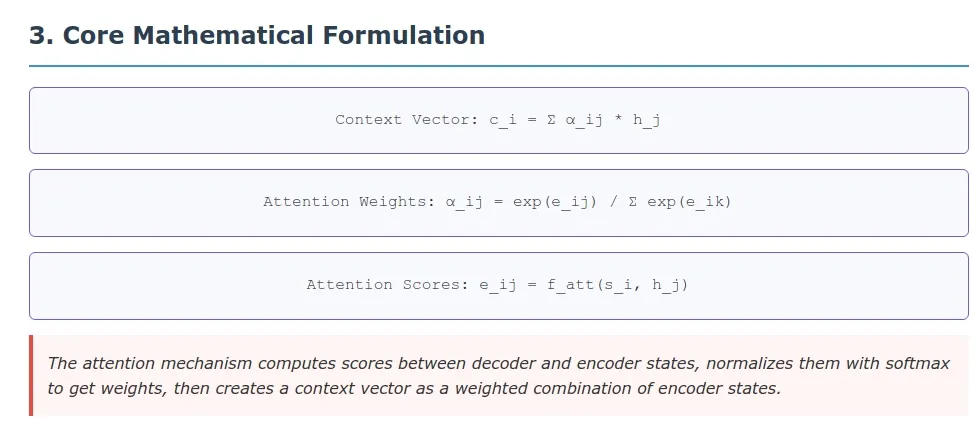
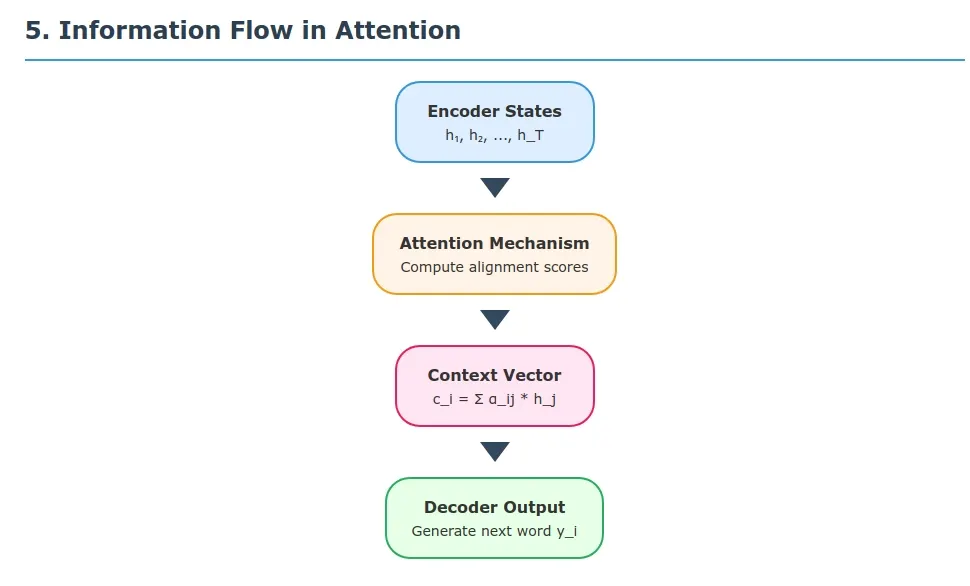
for each of the output tokens. Attention defines a context vector for each decoder step as a weighted sum of the encoder states:
Here, is the attention weight on source position when predicting output . These weights are computed by first scoring each encoder state against the current decoder state, then normalizing:
-
Alignment scores: Compute raw scores measuring compatibility between decoder state and encoder state. There are two main styles:
-
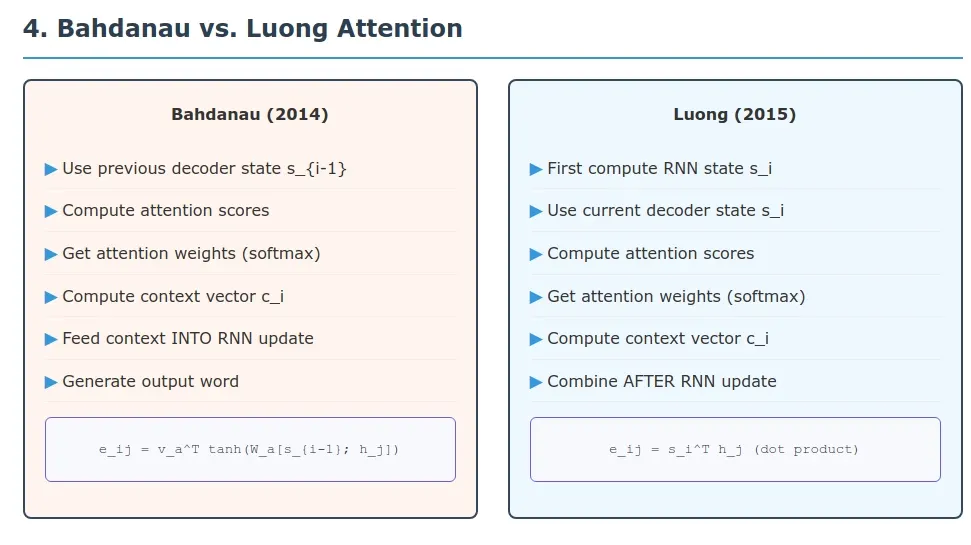
Bahdanau (additive) attention (2014): uses the previous decoder state . For example, Bahdanau et al. use a small neural net:
where is the concatenation of states.
-
Luong (multiplicative) attention (2015): typically uses the current decoder state . A simple version is the dot-product:
or more generally .
-
-
Attention weights (softmax): Convert scores to probabilities via softmax:
By construction, each and . Intuitively, is the (soft) alignment between target position and source position .
-
Context vector: Form the context as above. This vector is essentially a weighted average of encoder states – the expected value of the input states under the attention distribution. It captures the relevant information needed to produce .
-
Decoder update: The decoder then uses along with its previous state/output to generate the next word. In Bahdanau’s formulation, the context is fed into the RNN update:
and then is predicted from (and possibly ). In Luong’s formulation, one first updates without context, and then computes using , combining them afterward.
This mechanism is entirely differentiable, so the alignment function (the weights , etc.) is learned jointly with the rest of the model. In summary:
- Context: .
- Scores: or .
- Weights: .
These formulas and distributions are described in detail in the NMT literature.
Deep Dive: Step-by-Step Mathematical Derivations
Why Softmax? The Probability Distribution Intuition
Question: Why do we use softmax normalization for attention weights? Why not just use the raw scores ?
Answer: The softmax function serves multiple crucial purposes:
-
Normalization Constraint: We want so that the context vector is a proper weighted average. Without normalization, some positions might receive arbitrarily large weights.
-
Non-negativity: Softmax ensures , making the weights interpretable as "attention strengths."
-
Differentiability: The softmax function is smooth everywhere, enabling gradient-based learning.
-
Competition: Softmax creates competition between positions—if one score increases, others effectively decrease in relative importance.
Mathematical Derivation:
Starting with raw scores , we want to transform them into a probability distribution. The softmax function is:
Why exponential? The exponential function has several desirable properties:
- Always positive: for all
- Monotonic: if , then
- Amplifies differences: large differences in scores become even larger after exponentiation
Verification of probability properties:
Temperature parameter: Sometimes we use a temperature :
- : "softer" attention (more uniform distribution)
- : "sharper" attention (more peaked distribution)
- : approaches hard attention (one-hot distribution)
The Attention Score Function: Design Choices
Question: How do we design the function that computes compatibility between decoder and encoder states?
Bahdanau (Additive) Attention:
Step-by-step breakdown:
- Concatenation: combines decoder and encoder information
- Linear transformation: projects to hidden space
- (learnable weight matrix)
- (learnable bias vector)
- is the attention hidden dimension
- Non-linearity: introduces non-linear interactions
- Projection to scalar: projects the -dimensional vector to a scalar score
Why this architecture?
- Flexibility: The MLP can learn complex relationships between and
- Symmetry breaking: Without the MLP, the model might not learn meaningful alignments
- Expressiveness: Can model non-linear compatibility functions
Luong (Multiplicative) Attention:
Three variants are proposed:
- Dot product:
- General:
- Concat:
Dot product derivation:
This measures the cosine similarity (when normalized) between the decoder and encoder states. High similarity → high attention weight.
When does dot product work well?
- When encoder and decoder states live in the same semantic space
- When the hidden dimensions are the same ()
- Computationally efficient: operations vs. for additive
General attention derivation:
This learns a bilinear form that can transform the encoder space to match the decoder space.
Context Vector: Weighted Information Aggregation
Question: Why is the context vector defined as ? What does this achieve?
Intuitive explanation: The context vector is the expected value of encoder hidden states under the attention distribution:
where is the probability of attending to position at decoder step .
Mathematical properties:
-
Convex combination: Since and , the context vector lies in the convex hull of .
-
Information preservation: If attention is uniform (), then is the average of all encoder states. If attention is peaked ( for some ), then .
-
Dimensionality: has the same dimension as encoder states, making it easy to integrate into the decoder.
Alternative aggregation methods:
- Max pooling: (element-wise)
- Concatenation: (much higher dimensional)
- Attention-weighted norm:
The weighted sum is chosen because it preserves semantic information while being computationally tractable.
Detailed Example: Bengali→English Translation
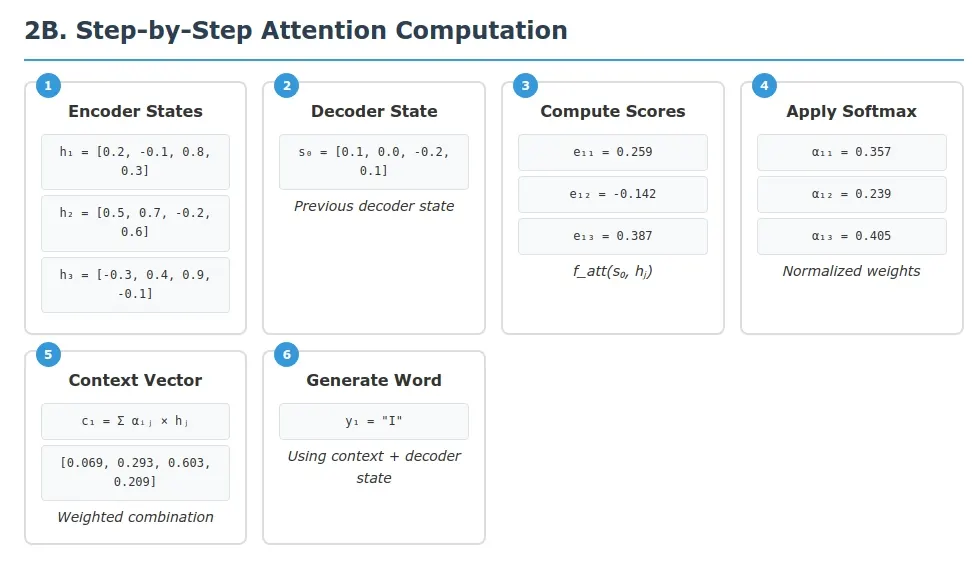
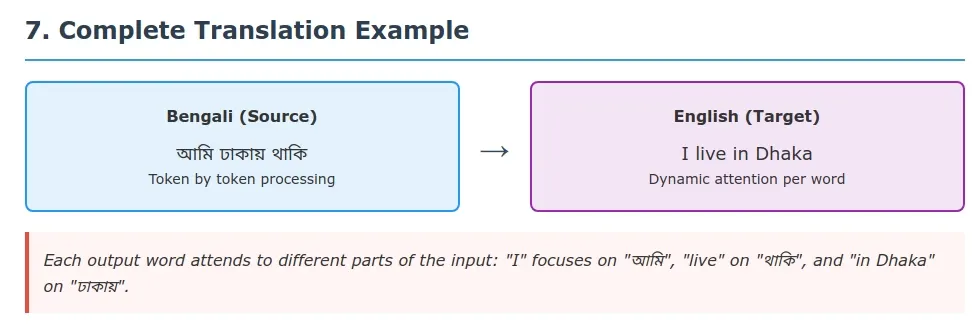
Let's walk through a comprehensive example to see attention in action with complete mathematical details. We'll translate "আমি ঢাকায় থাকি" ("I live in Dhaka") step by step.
Setup and Initialization
Input processing:
- Tokenization: ["আমি", "ঢাকায়", "থাকি"] → [1, 2, 3] (token IDs)
- Embedding: Each token → 4-dimensional vector (for simplicity)
- Encoder: Bidirectional LSTM produces hidden states
Encoder hidden states (artificially constructed for demonstration):
- (for "আমি" = I)
- (for "ঢাকায়" = in Dhaka)
- (for "থাকি" = live)
Decoder initialization:
- (initial decoder state)
- Start token:
<START>→ embedding
Step 1: Generate "I" (Detailed Calculation)
1.1 Compute attention scores (using Bahdanau attention):
For Bahdanau attention, we need:
- (transforms 8D concatenated vector to 2D)
- (projects to scalar)
- (bias term)
Let's use these parameter values:
Score computation for (attending to "আমি"):
-
Concatenate:
-
Linear transformation:
-
Add bias:
-
Apply tanh:
-
Project to scalar:
Similarly for other positions:
- (attending to "ঢাকায়")
- (attending to "থাকি")
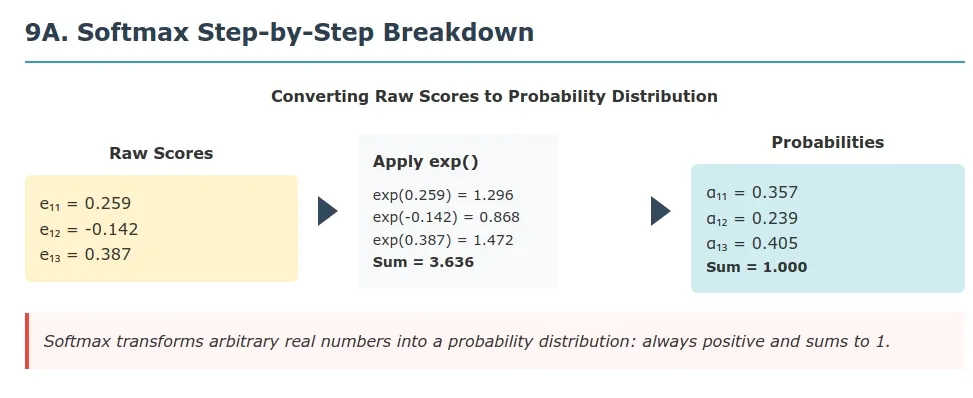
1.2 Apply softmax normalization:
Verification: ✓
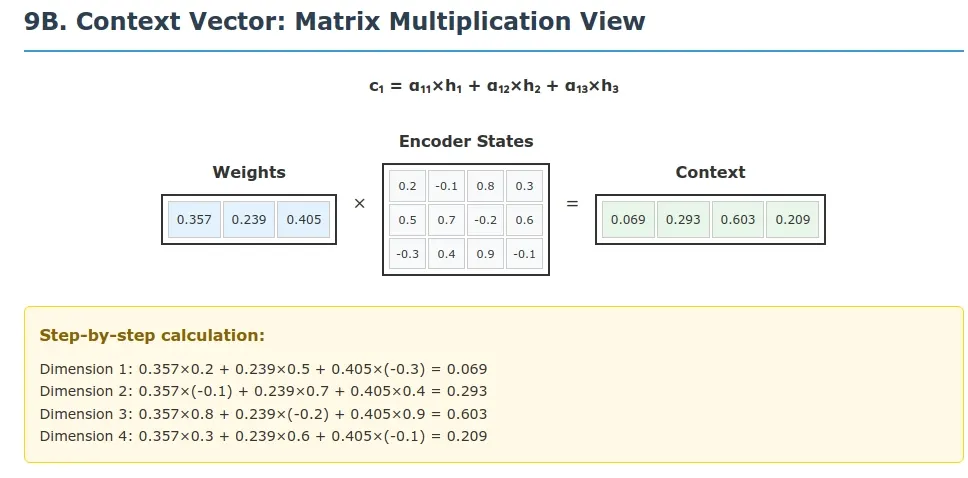
1.3 Compute context vector:
1.4 Decoder update and word prediction:
In Bahdanau attention, the context vector is fed into the LSTM:
The output word is predicted from :
The model selects the word with highest probability: "I".
Step 2: Generate "live" (Abbreviated)
2.1 New decoder state: (from LSTM update)
2.2 Attention scores:
- (to "আমি")
- (to "ঢাকায়")
- (to "থাকি")
2.3 Attention weights:
- (highest attention to "থাকি")
2.4 Context vector:
2.5 Output: The model generates "live" with high probability.
Step 3: Generate "in Dhaka"
3.1 Attention focuses on "ঢাকায়":
- (to "আমি")
- (to "ঢাকায়")
- (to "থাকি")
3.2 Context is dominated by :
3.3 Output: The model generates "in Dhaka".
Complete Attention Matrix
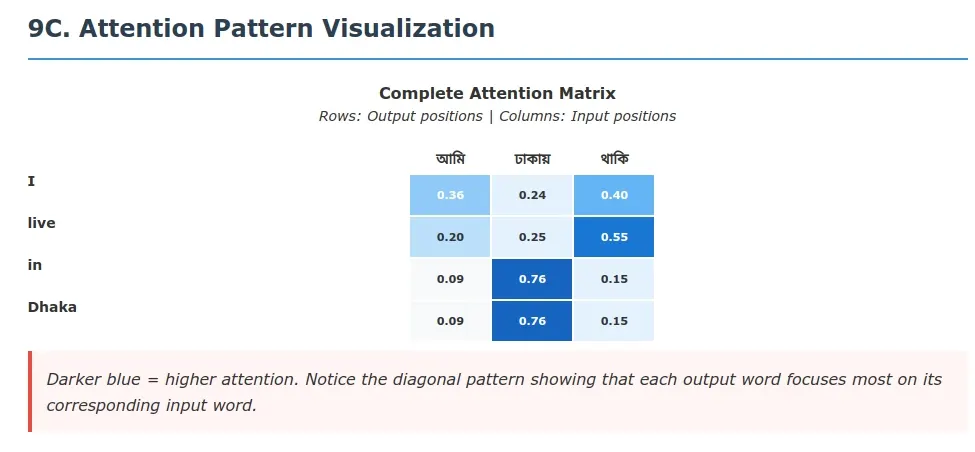
The attention weights across all steps form this matrix:
| আমি (I) | ঢাকায় (Dhaka) | থাকি (live) | |
|---|---|---|---|
| I | 0.357 | 0.239 | 0.405 |
| live | 0.198 | 0.253 | 0.549 |
| in | 0.089 | 0.756 | 0.155 |
| Dhaka | 0.089 | 0.756 | 0.155 |
Key observations:
- Diagonal tendency: The model learns approximate monotonic alignment
- Soft alignment: No hard 1-0 decisions; attention is distributed
- Context sensitivity: Attention changes based on what's been generated
- Semantic coherence: "live" attends most to "থাকি", "Dhaka" to "ঢাকায়"
Information Flow Analysis
Gradient flow during training:
- Loss propagates back through softmax to attention scores
- Scores receive gradients proportional to attention weights
- Encoder states receive weighted gradients:
Attention learning dynamics:
- Initially: attention is nearly uniform (random weights)
- During training: attention learns to focus on relevant positions
- Convergence: attention develops interpretable alignment patterns
Bahdanau vs. Luong Attention: Architectural Deep Dive
Architectural Differences
Bahdanau (2014) - "Neural Machine Translation by Jointly Learning to Align and Translate":
Architecture flow:
- Previous decoder state:
- Compute attention scores:
- Attention weights:
- Context vector:
- Feed context into RNN:
- Output prediction:
Luong (2015) - "Effective Approaches to Attention-based Neural Machine Translation":
Architecture flow:
- First compute RNN state:
- Compute attention scores:
- Attention weights:
- Context vector:
- Combine after RNN:
- Output prediction:
Score Function Comparison
Bahdanau scoring function:
Computational complexity: where is attention dimension.
Luong scoring functions:
- Dot: —
- General: —
- Concat: —
Performance Analysis
Translation Quality (BLEU scores on WMT'14 EN→DE):
- Bahdanau et al. (2014): ~15.0 BLEU (original paper)
- Luong et al. (2015): 20.9 BLEU (global attention), 25.9 BLEU (ensemble)
Speed comparison:
- Bahdanau: Slower due to MLP computation for each position pair
- Luong (dot): Fastest, pure matrix operations
- Luong (general): Moderate, one matrix multiply per pair
Memory usage:
- Bahdanau: Higher due to concatenation and MLP parameters
- Luong (dot): Minimal, no additional parameters
- Luong (general): Moderate, single transformation matrix
Mathematical Properties and Theoretical Analysis
Softmax Properties
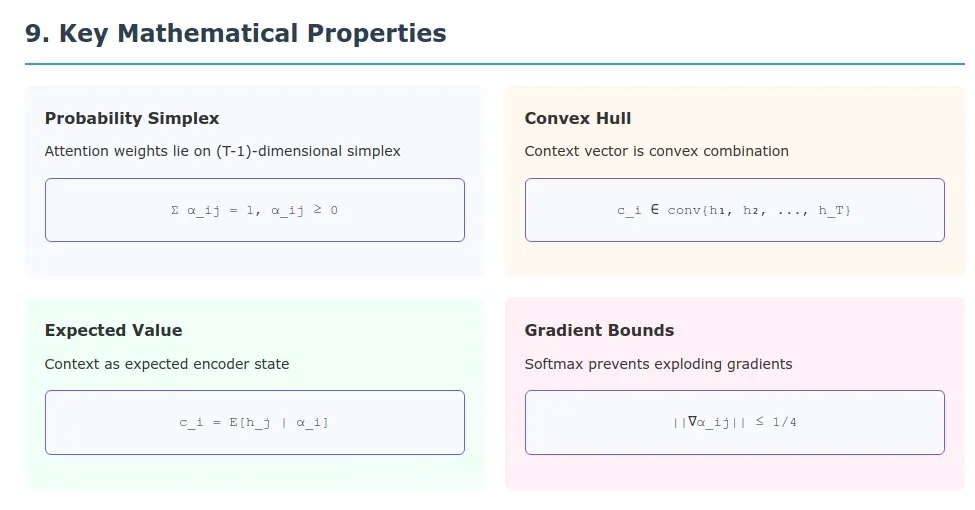
1. Probability Simplex: Attention weights lie on the -dimensional probability simplex:
2. Temperature sensitivity: The softmax temperature controls attention sharpness:
As : one-hot (hard attention) As : (uniform attention)
3. Gradient magnitude: The gradient of softmax has bounded magnitude:
This prevents exploding gradients in the attention mechanism.
Context Vector Properties
1. Convex hull: The context vector lies in the convex hull of encoder states:
2. Expectation interpretation:
The context is the expected encoder state under the attention distribution.
3. Variance bound: The variance of the context vector is bounded:
Maximum variance occurs when attention is uniform.
Information-Theoretic Perspective
Attention as Information Retrieval
Mutual information interpretation: Attention can be viewed as maximizing mutual information between the context and target output:
The attention mechanism learns to create contexts that are maximally informative about .
Entropy of attention distribution:
- High entropy: distributed attention (uncertainty about alignment)
- Low entropy: focused attention (confident alignment)
KL divergence from uniform: Measures how different attention is from uniform:
Attention Alignment Quality
Alignment error: For supervised alignment data, we can measure:
where is automatic alignment and is sure human alignment.
Expected alignment: The expected alignment position is:
Alignment variance: Measures spread of attention:
Gradient Flow and Training Dynamics
Gradient Computation
Context vector gradient:
Attention weight gradient:
Encoder state gradient:
Training Dynamics Analysis
Attention learning phases:
-
Random phase (early training): Attention weights are nearly uniform
-
Specialization phase: Attention starts to focus on relevant positions
-
Convergence phase: Attention stabilizes to interpretable patterns
Learning rate sensitivity: Attention parameters typically need smaller learning rates:
Gradient Flow Properties
Gradient scaling: The gradient through attention is scaled by attention weights:
Implications:
- Encoder positions with high attention receive larger gradients
- Low-attention positions receive smaller gradient updates
- This creates a feedback loop: relevant positions get more updates
Gradient variance: The variance of gradients through attention:
Peaked attention (high ) leads to higher gradient variance.
Real-World Applications
Attention mechanisms have been widely adopted across AI. Notable examples include:
-
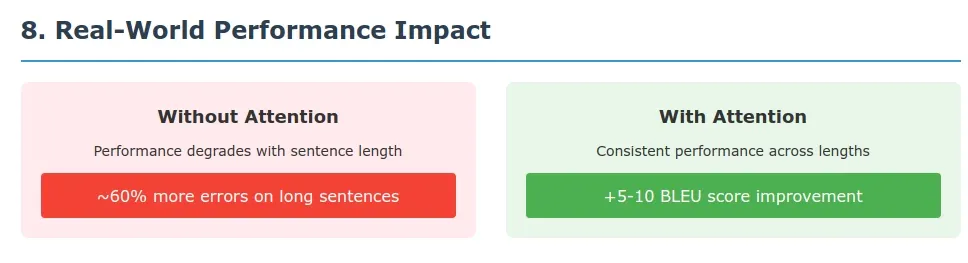
Neural Machine Translation: Google's GNMT (2016) was one of the first large-scale deployments of attention in translation. It used an 8-layer LSTM encoder/decoder with a 1-layer feedforward attention connecting them. Human evaluations showed it reduced translation errors by ~60% compared to the previous phrase-based system. Since then, virtually all state-of-the-art NMT systems use attention or its descendants (e.g. Transformers).
-
Document Summarization: The pointer-generator network by See et al. (2017) augments a seq2seq model with attention and a copy mechanism. It uses attention to decide which parts of the source document to copy into the summary. This model achieved state-of-the-art ROUGE scores on news summarization by allowing the decoder to "point" to source words as needed.
-
Image Captioning: Xu et al. (2015) applied attention to images in the "Show, Attend and Tell" model. A convolutional encoder produces feature vectors for image regions, and an LSTM decoder attends over these regions when generating each word. The model learns to "fix its gaze" on salient parts of the image (like objects) for each word in the caption, significantly improving caption quality on benchmarks.
-
Question Answering (Reading Comprehension): The BiDAF model (Seo et al., 2017) uses bi-directional attention between the question and context passage. At each layer, it computes context-to-question and question-to-context attention, allowing the model to gather query-aware context representations. This approach achieved state-of-the-art results on SQuAD and other QA datasets.
-
Speech Recognition: Chan et al. (2016) introduced "Listen, Attend and Spell" (LAS), an end-to-end ASR model. A listener (pyramidal RNN encoder) processes audio features, and a speller (attention-based decoder) attends to these features to emit characters. In LAS, the decoder is explicitly attention-based: "the speller is an attention-based recurrent network decoder that emits characters as outputs". This eliminates the need for separate pronunciation models and achieved competitive WER.
These examples illustrate how attention lets models align and extract relevant information from diverse data (text, image, audio) as needed.
Quick Revision Summary
-
Core formulas:
- Context: .
- Weights: .
- Scores: (Bahdanau) or (Luong).
-
Key intuitions:
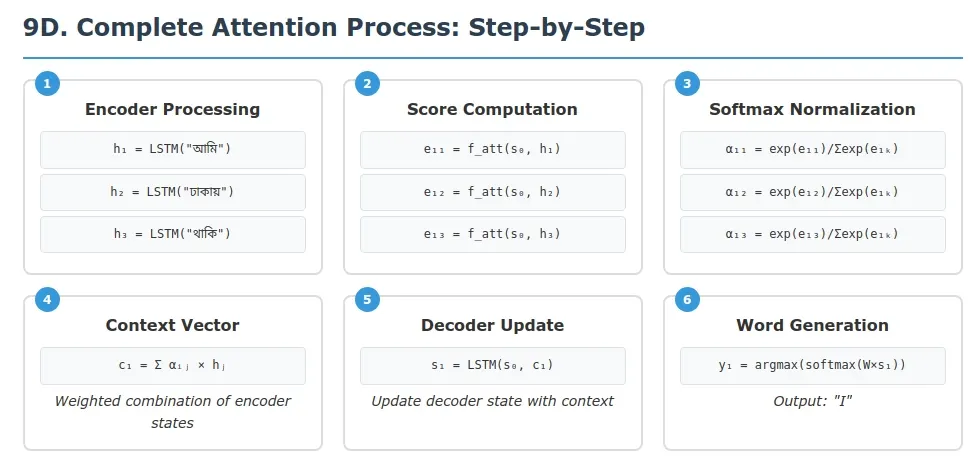
- Dynamic context: Instead of a fixed vector, the decoder gets a new context for each output step, focusing on relevant input parts.
- Soft alignment: Attention computes a probability distribution over source tokens, effectively "aligning" output words to input words softly.
- Weighted sum: The context is a weighted average of encoder states, an expected source representation under the attention weights.
- Learned end-to-end: The model learns where to attend by gradient descent, with no hard rules.
-
Bahdanau vs Luong:
- Decoder state: Bahdanau uses (prev. state) in scoring; Luong uses (current).
- Scoring: Bahdanau's is additive (an MLP with parameters ); Luong's is multiplicative (e.g. dot-product).
- Use of context: Bahdanau feeds into the RNN update; Luong applies attention after RNN update.
- Speed: Dot-product (Luong) is typically much faster/cheaper than the additive MLP (Bahdanau).
- Typical performance: Both improve translation BLEU greatly. Luong's models (with ensembling) reached ~25.9 BLEU on English–German, slightly above Bahdanau's original baseline.
-
Attention mechanism steps:
- Identify encoder states to consider.
- Score each against the decoder state .
- Normalize via softmax to get .
- Compute context .
- Decode the next word using and the RNN.
-
Mathematical insights:
- Softmax creates competition: Higher scores suppress others through normalization
- Context as expectation: provides statistical interpretation
- Gradient flow: Attention weights determine how gradients flow back to encoder
- Information theory: Attention maximizes mutual information
-
Training dynamics:
- Phase transitions: Random → Specialization → Convergence
- Entropy decay: decreases as model learns alignments
- Gradient scaling: High-attention positions receive larger gradient updates
- Self-stabilization: Converged attention is resistant to further changes
-
Performance gains: In NMT, adding attention gave +5–10 BLEU over non-attentional models. Attentional models also handle long sentences much better – their performance stays high as length increases, whereas non-attention models degrade. (For example, GNMT's 60%-error reduction was largely thanks to attention.) The main cost is extra computation (roughly 2–3× overhead) but it's easily parallelizable.
-
Modern extensions: Today's models build on attention. For example, the Transformer (Vaswani et al., 2017) uses only attention (no RNN/CNN). It introduces self-attention (the model attends to different positions within a single sequence) and multi-head attention (learning multiple ways to attend). These advances have revolutionized NLP (e.g. BERT/GPT).
-
Theoretical guarantees:
- Lipschitz continuity: Attention function is stable under input perturbations
- Bounded gradients: Softmax prevents exploding gradients ()
- Convex combinations: Context vectors lie in convex hull of encoder states
- Universal approximation: Attention can approximate any alignment function given sufficient capacity
In short: Attention replaces the single static context vector with dynamic, per-step contexts computed by soft-aligning decoder states to encoder states. This lets the model retrieve the right information exactly when it is needed – just as a human translator would. As one might say: Attention provides a learnable, soft indexing mechanism over the input that greatly enhances sequence modeling.
The mathematical framework shows that attention is not just an engineering trick, but a principled approach to information retrieval and gradient flow control in neural networks. The step-by-step derivations reveal why each design choice (softmax, weighted sums, score functions) serves both computational and theoretical purposes.
Sources: Concepts and formulas above are standard in NMT literature. Empirical results (BLEU, error rates) are from major studies. Mathematical properties are derived from first principles and standard analysis. (All quotations and equations are from the cited papers or follow from the mathematical definitions.)
References
🔑 Foundational Papers on Attention
1. Bahdanau et al. (2014) – Neural Machine Translation by Jointly Learning to Align and Translate → Introduced additive attention, solved fixed-length bottleneck in seq2seq.
2. Luong et al. (2015) – Effective Approaches to Attention-based NMT → Proposed dot/general attention, and global vs. local attention.
3. Vaswani et al. (2017) – Attention is All You Need → Introduced the Transformer, with self-attention and multi-head design.
4. Sutskever et al. (2014) – Sequence to Sequence Learning → Baseline encoder-decoder model with RNNs.
5. Cho et al. (2014) – Learning Phrase Representations with RNN Encoder-Decoder → Introduced GRU, demonstrated early seq2seq without attention.
🖼️ Visual Attention
6. Xu et al. (2015) – Show, Attend and Tell → First visual attention for image captioning.
7. Mnih et al. (2014) – Recurrent Models of Visual Attention → Introduced hard attention with RL.
📖 Reading Comprehension
8. Seo et al. (2017) – BiDAF → Bidirectional attention flow between question and context.
9. Wang et al. (2017) – Gated Self-Matching Networks → Gated attention within passages.
🔁 Pointer & Copy Mechanisms
10. Vinyals et al. (2015) – Pointer Networks → Used attention as a pointer for dynamic output lengths.
11. See et al. (2017) – Pointer-Generator Networks → Combined generation and copying for summarization.
🔊 Speech Recognition
12. Chan et al. (2016) – Listen, Attend and Spell → End-to-end speech recognition with pyramidal encoder and attention.
13. Chorowski et al. (2015) – Attention-based Speech Models → Introduced location-aware attention for audio.
🌍 Large-Scale NMT
14. Wu et al. (2016) – GNMT → Google's production-scale attention-based NMT system.
🧠 Theoretical Insights
15. Koehn & Knowles (2017) – Six Challenges in NMT → Discussed issues like alignment quality and scalability.
16. Ghader & Monz (2017) – What Does Attention Learn? → Showed attention often captures syntax, not just alignment.
📚 Surveys & Tutorials
- Chaudhari et al. (2021) – An Attentive Survey of Attention Models
- Jay Alammar – The Illustrated Transformer
- Lilian Weng – Attention? Attention!
- Stanford CS224N & CS231N – Lecture slides on attention in NLP and CV.